Anthropic's Claude Opus 4.5 can tackle some tasks lasting nearly five hours

AI research organization METR has released new benchmark results for Claude Opus 4.5. Anthropic's latest model achieved a 50 percent time horizon of roughly 4 hours and 49 minutes—the highest score ever recorded. The time horizon measures how long a task can be while still being solved by an AI model at a given success rate (in this case, 50 percent).
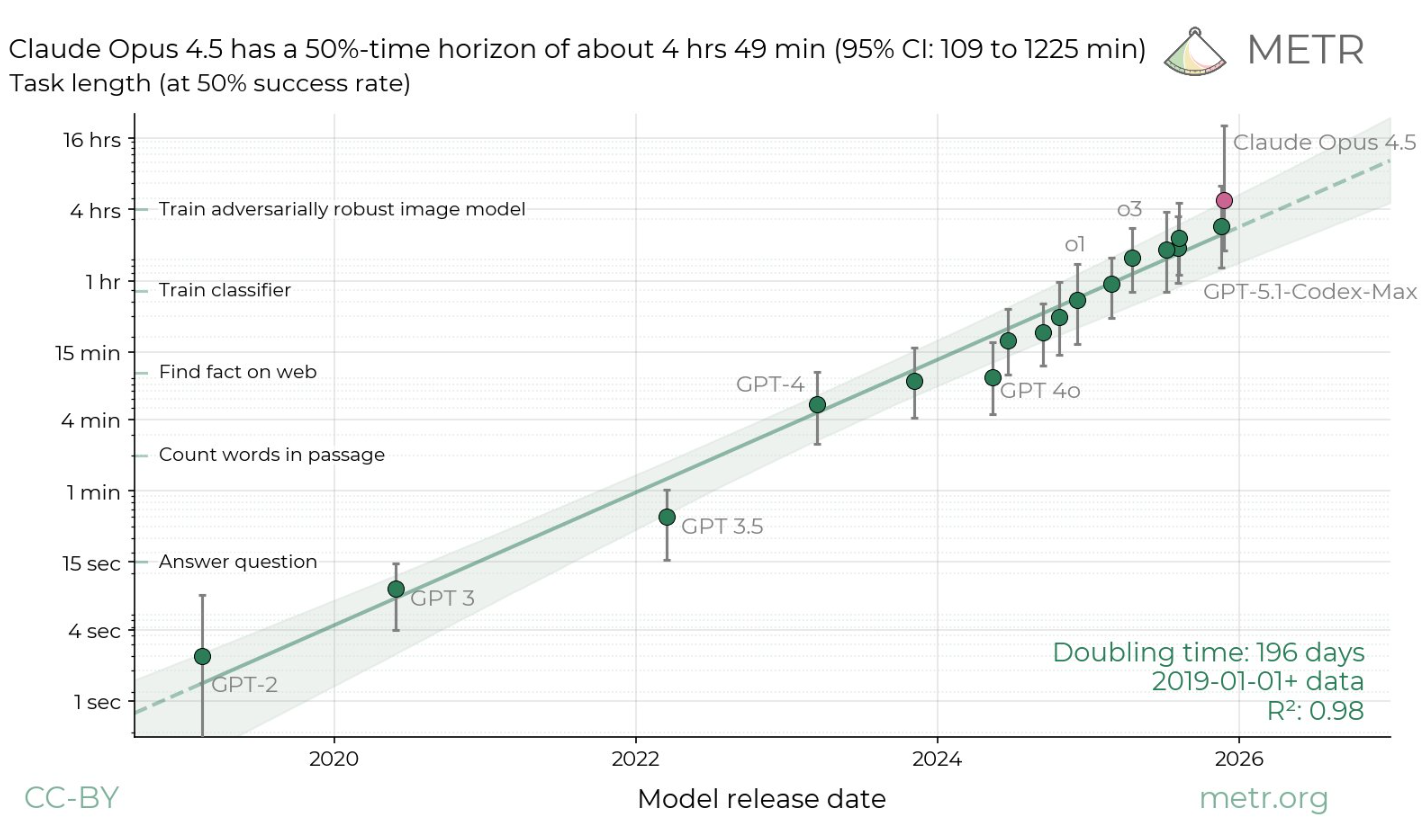
The gap between difficulty levels is big. At the 80 percent success rate, the time horizon drops to just 27 minutes, about the same as older models, so Opus 4.5 mainly shines on longer tasks. The theoretical upper limit of over 20 hours is likely noise from limited test data, METR says.
Like any benchmark, the METR test has its limits, most notably, it only covers 14 samples. A detailed breakdown by Shashwat Goel of the weaknesses is here.
AI News Without the Hype – Curated by Humans
Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section.
Subscribe nowRead on for the full picture.
Subscribe for hype-free coverage.
- Full access to every article on THE DECODER
- No ads
- Join the comments and community discussions
- A weekly AI news recap via mail
- 6x/year: "AI Radar" — deep dives on the AI topics that matter most
- Daily AI news, always up to date
- Our full ten-year archive
- Covered by a team with 10+ years in AI