Cohere's new vision model can process images, diagrams, PDFs, and other types of visual data

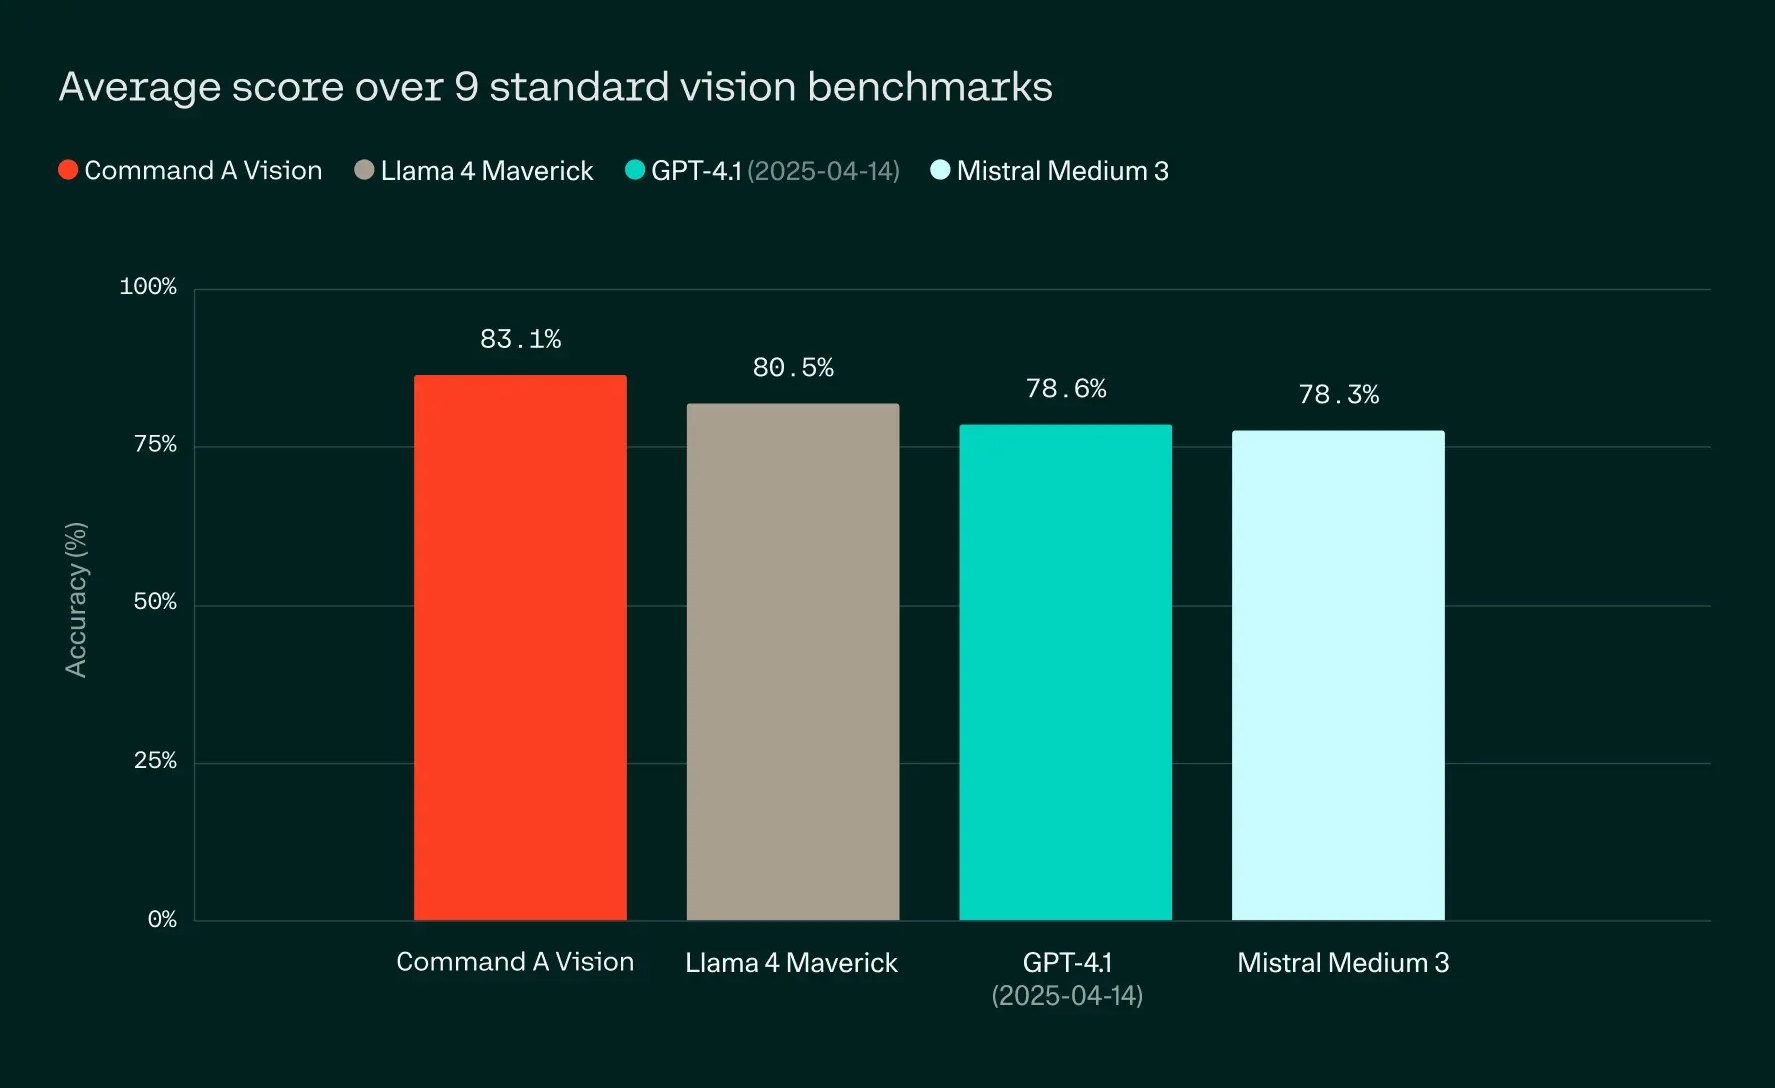
Cohere's new Command A Vision model is designed to handle images, diagrams, PDFs, and other types of visual data. Cohere says the model outperforms GPT-4.1, Llama 4 Maverick, Pixtral Large, and Mistral Medium 3 on standard vision benchmarks.
The model's OCR can recognize both the text and the structure of documents such as invoices and forms, outputting the extracted data in structured JSON. Command A Vision can also process real-world images, like identifying potential risks in industrial environments, the company says.
Command A Vision is available through the Cohere platform and for research on Hugging Face. The model can run locally with either two A100 GPUs or a single H100 using 4-bit quantization.
AI News Without the Hype – Curated by Humans
Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section.
Subscribe nowRead on for the full picture.
Subscribe for hype-free coverage.
- Full access to every article on THE DECODER
- No ads
- Join the comments and community discussions
- A weekly AI news recap via mail
- 6x/year: "AI Radar" — deep dives on the AI topics that matter most
- Daily AI news, always up to date
- Our full ten-year archive
- Covered by a team with 10+ years in AI