Reasoning models like Claude Sonnet 4.5 are getting better at spotting security flaws

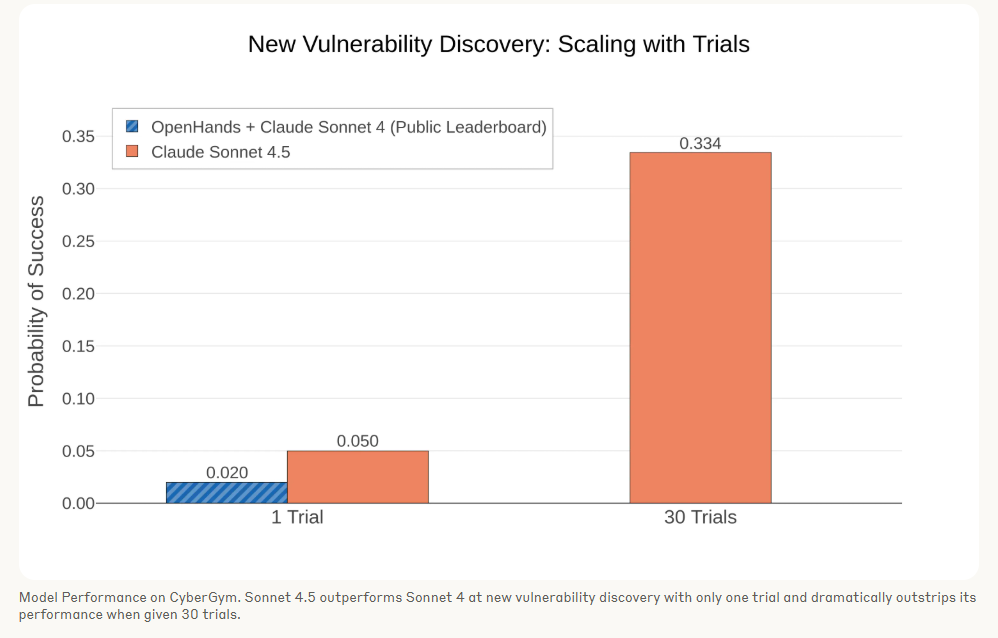
Anthropic sees growing potential for language models in cybersecurity. The company cites results from the CyberGym leaderboard: Claude Sonnet 4 uncovers new software vulnerabilities about 2 percent of the time, while Sonnet 4.5 increases that rate to 5 percent. In repeated tests, Sonnet 4.5 finds new vulnerabilities in more than a third of projects.
In a recent DARPA AI Cyber Challenge, Anthropic notes that teams used large language models like Claude "to build 'cyber reasoning systems' that examined millions of lines of code for vulnerabilities to patch." Anthropic calls this a possible "inflection point for AI’s impact on cybersecurity."
AI News Without the Hype – Curated by Humans
Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section.
Subscribe nowRead on for the full picture.
Subscribe for hype-free coverage.
- Full access to every article on THE DECODER
- No ads
- Join the comments and community discussions
- A weekly AI news recap via mail
- 6x/year: "AI Radar" — deep dives on the AI topics that matter most
- Daily AI news, always up to date
- Our full ten-year archive
- Covered by a team with 10+ years in AI